PackLM
The 80% Smaller JSON Alternative for LLMs
AI tooling / Open Source
PackLM
About the project
PackLM is an innovative data serialization format specifically designed for Large Language Models. By separating the schema from the actual data into a plain text format, it reduces token usage by up to 80% compared to standard JSON when sending structured data to AI models, significantly cutting down API costs and latency.
The Challenge
When building applications powered by Large Language Models (LLMs), developers typically rely on JSON to send structured data to the model.
However, JSON is notoriously verbose. Every single object repeats its keys (e.g., `{"name": "Alice", "age": 25}, {"name": "Bob", "age": 30}`). When sending arrays with hundreds or thousands of items to an LLM, this repetition consumes a massive amount of tokens.
This leads to two major problems:
- High Costs: You pay for every token sent to the API.
- Context Limits & Latency: Verbose JSON eats up the context window quickly and slows down the time-to-first-token.
The Solution
I built PackLM to solve the token bloat issue. It works by completely decoupling the data schema from the actual values.
Instead of repeating keys, PackLM defines the structure once at the top, and then lists the values in a highly compressed, CSV-like plain text format that LLMs naturally understand.
Key Achievements:
- Achieved up to 80% reduction in token usage compared to standard minified JSON.
- Built a lightweight parser/serializer that seamlessly integrates into existing AI pipelines.
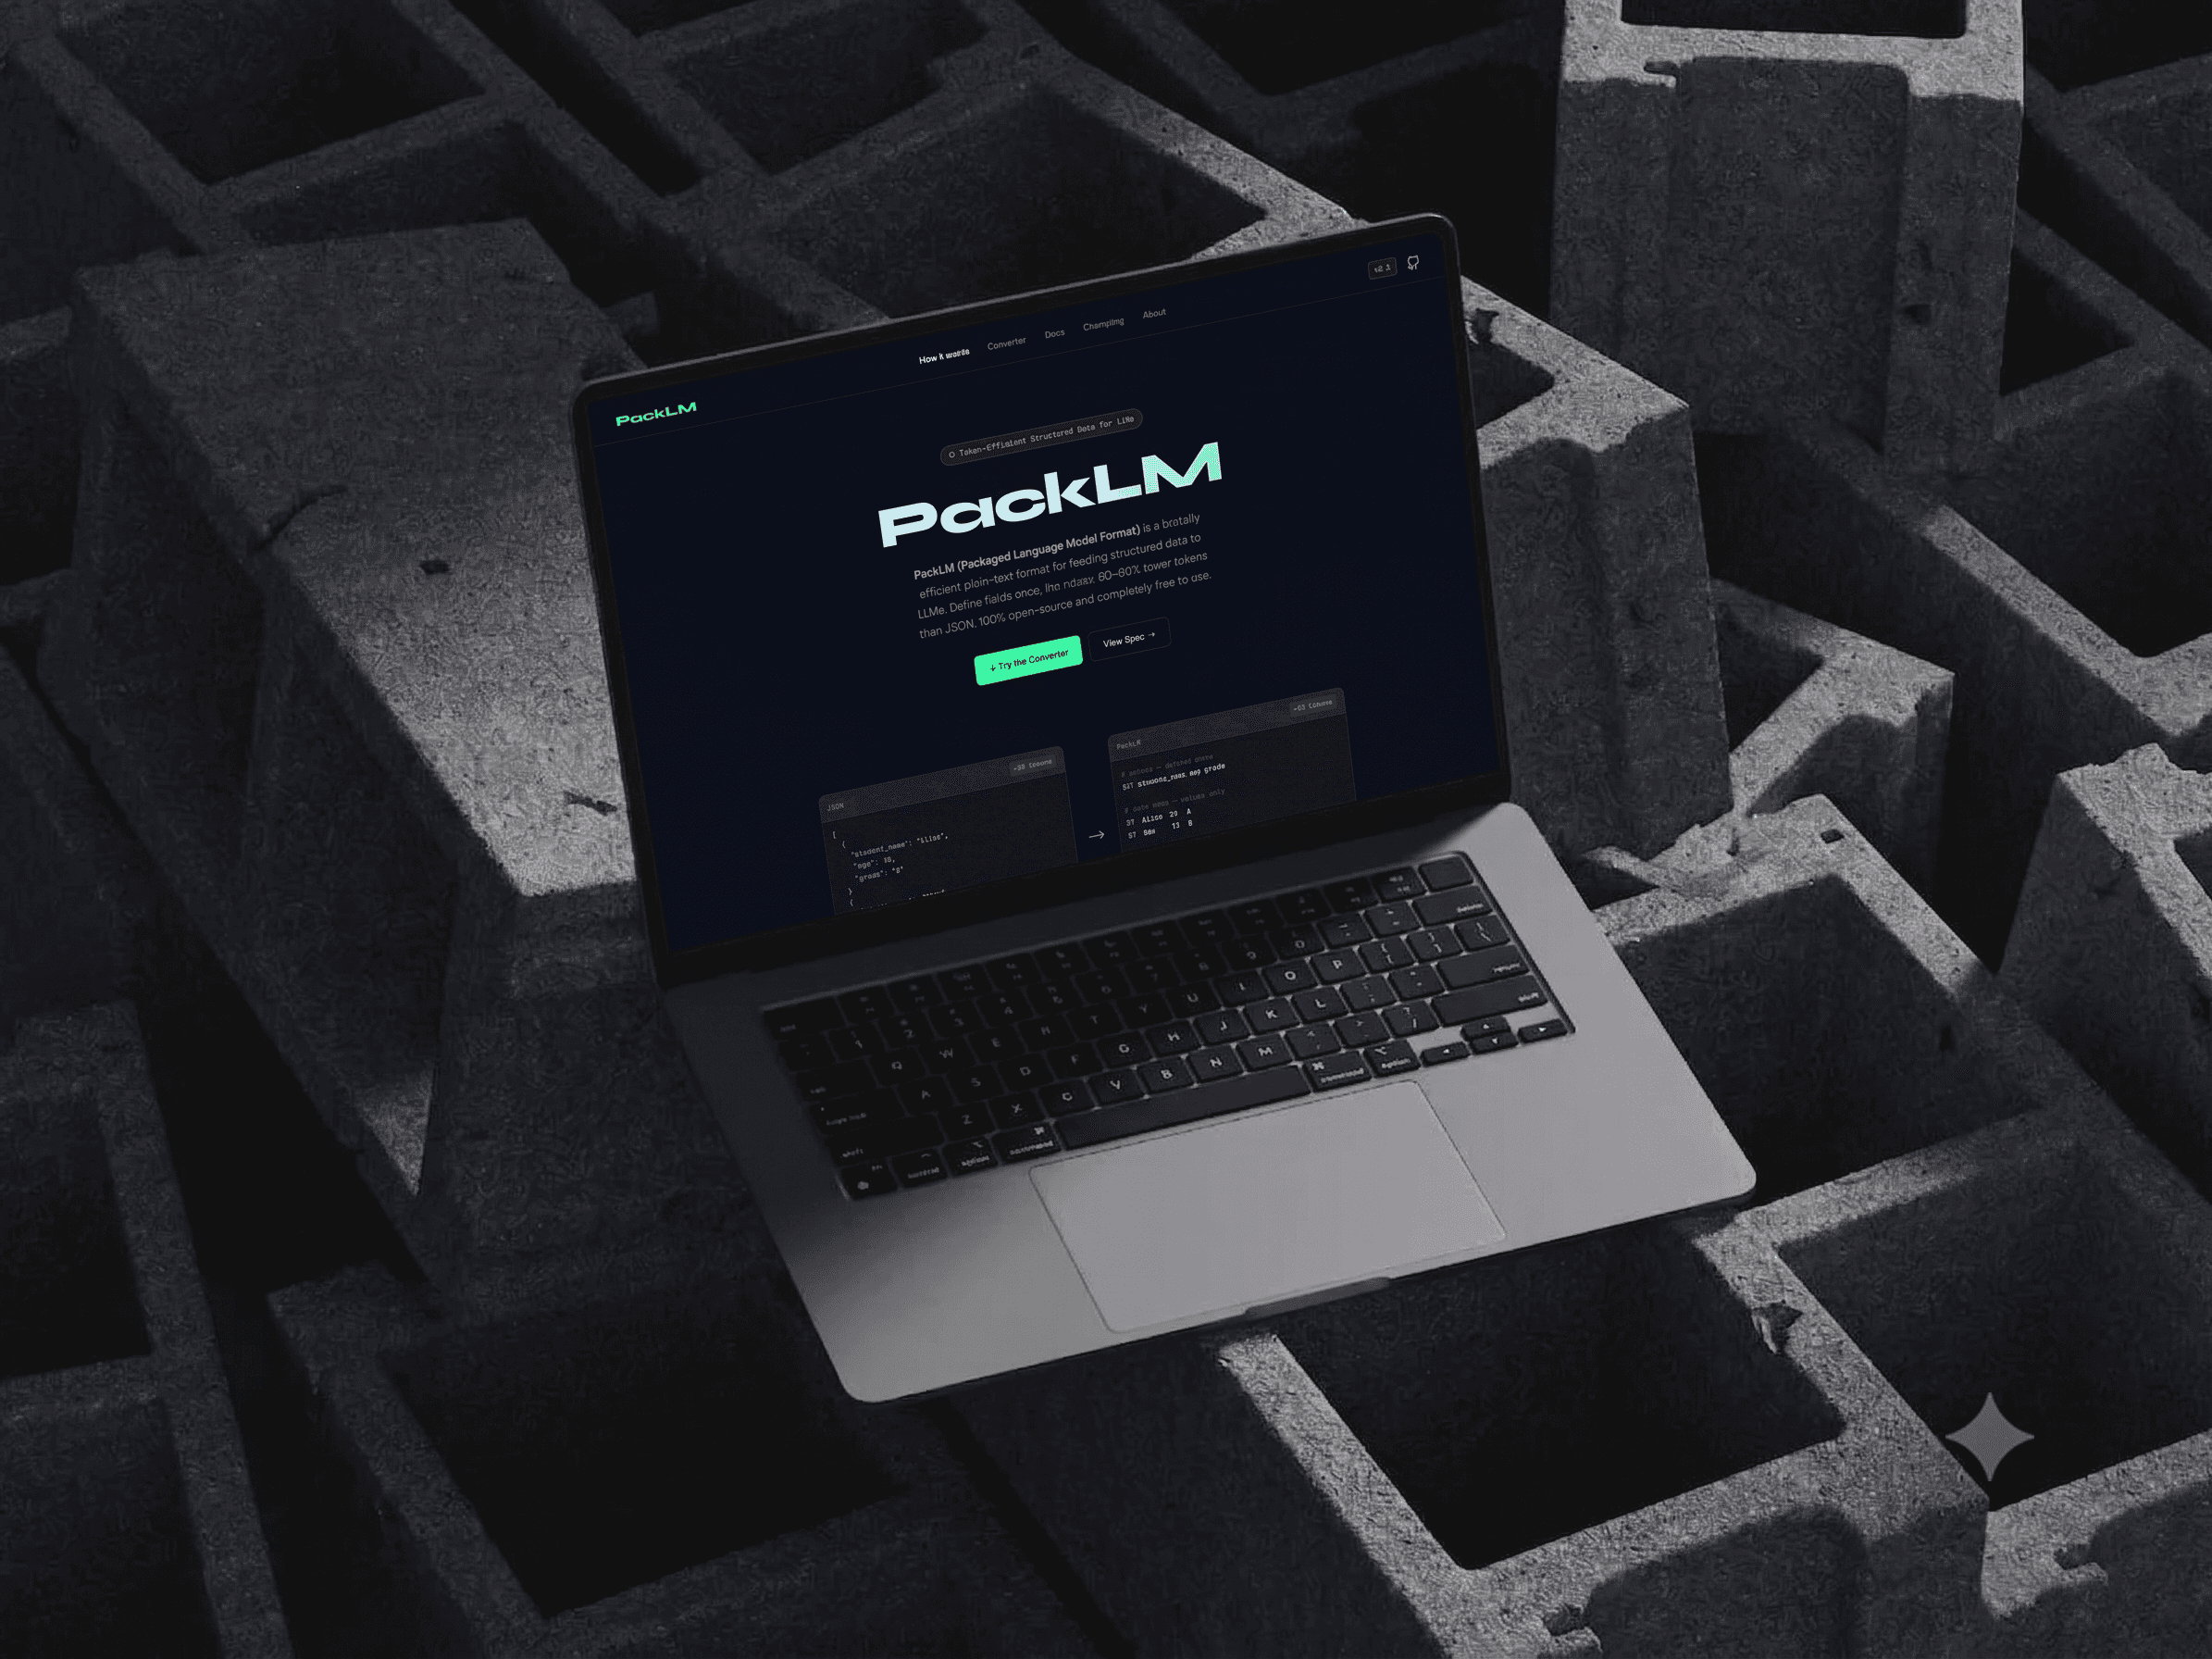
- Designed a modern, interactive landing page to demonstrate the token savings in real-time.
No gallery images available